Open

Workspace · last 7 days

AIR Core Feature workspace

Operational availability, effectiveness, and the work that needs a decision.

Effective availability
88.9%
Effective availability
=
96.2%
Uptime × quality of uptime
×
92.4%
Success within bounds

Service uptime is 99.97%. The 11-point gap is failures, retries, and out-of-bound cost or latency — the work AIR is for.

OAE
66.6%
A 99.2 × P 71.0 × Q 94.5
Band 1 open
3
Safety & compliance modes
COPQ · quarter
$32.5k
31% of inference spend
Verified fixes · qtr
2
MTTR-E 11.5 days

Effectiveness by system

Workspace OAE 66.6%. Performance is where the spend hides; Quality is where the risk hides. Select a system for its full record.

From the record

Top of triage

Since yesterday

Overnight classification queued 1 new candidate
dead tool overhead · confidence 0.87
CA-0141 verdict landed: verified, −71%
$3,420/mo recovered · narrative attached
FM-D-0002 worsened again — 6.2/1k, +0.4 wk/wk
RCA open · forecast on the trend chart

Recent

Failure modes

Durable, versioned catalog of defects and waste with stable IDs across releases, model versions, and re-clusterings. Defects are tracked as event rates; waste is tracked as a level against your baseline.

Active modes
13
Defects
6
event-rate semantics
Waste
6
condition-level semantics
Safety-relevant
4
independent of class
Mitigated · retired
1
Agent over-capable routing and appraisal overhead have moved together for 12 weeks (r 0.81) — both trace back to the router policy. One causal edge would let CA-0149 verify against both.
Modes
IDFailure modeClassSafetySystem SeverityDetectionOccurrenceCriticality Cost impactStatus

Classification Queue

Incoming events are classified against existing modes and deduplicated automatically. Below the confidence threshold, candidates wait here for confirmation — your confirm/reject feeds the matcher. 30-day backfill complete: 41,208 events processed, 96.4% auto-attached.

Candidate new modes — 3 awaiting confirmation

Recently auto-attachedabove the 0.80 confidence threshold · content-addressed event IDs, append-only
EventWhenSystemSignal sourceAttached toConfidence

Reliability

Per-mode rate trending with model-version annotations. Rates are per 1,000 task attempts, scoped to the model version that produced them.

MOBF — mean operations between failures
Critical
4,120
vs floor 2,500 · inside the failure budget
Degraded
610
vs floor 400 · recovered after retry or below target
Escalations — working as designed
Escalation rate
2.6%
low-confidence outputs handed to a human
Escalation precision
91%
of handoffs genuinely needed the human
MTTR — mean time to repair
Recovery · in session
1.4 retries
median to self-correction (11 s)
Engineering · to verified fix
11.5 days
detection → verified corrective action
Availability
Effective
88.9%
success within cost + latency bounds
Service uptime
99.97%
the APM's number — the gap is AIR's

Agent watchlist — signals before they become modes

ROUTE-OPT · re-plan latency creeping +18% wk/wk
no quality impact yet · queues as a candidate if it crosses 0.60 confidence
0.44 · watching
TM-COPILOT · session length drifting up since prompt p-41
correlates with the held candidate — the 12-trace human read will settle both
0.52 · watching
SENTRY-VIS · fog-morning recall dips clustering
seasonal pattern · joins the FM-D-0002 RCA if it persists past two more weeks
0.38 · watching

These sit below the candidate threshold. The agent tracks each trajectory and queues a candidate the moment confidence crosses 0.60 — nothing is minted without a human confirm.

FM-D-0015 · Malformed JSON from parts-lookup tool — occurrences per 1,000 attempts, TM-COPILOT

Dashed markers: population-resetting events. Rate falls from 6.8 to 1.9 per 1,000 attempts after CA-0141 (tool-contract hardening) — the before/after delta feeding its verification verdict.

Effective availability — 12 weeks

The dashed line is service uptime. The space between the two lines is what uptime dashboards miss: failures, retries, and out-of-bound cost or latency.

Failure rate by system — per 1,000 attempts

SENTRY-VIS carries the dusk-drift surge; PREDICT-M's release gate keeps production near zero.

Where failures get caught

Later catches score worse on Detection. Moving catches up this list is what improves D — the loop-counter guardrail proposal moves FM-D-0022 from span analysis to in-session.

Reliability by systemweekly report slice · exportable
SystemEff. avail.MOBF crit.MOBF degr.MTTR-REscal.12-wk trend

Failure attribution — who actually owns it

Agent-attributable
model, prompt, or policy — counts against agent MOBF
61%
Upstream dependency
tool APIs, schema drift, rate limits — tagged, excluded from agent MOBF
27%
Input data
out-of-distribution or stale inputs — an intake governance problem
12%

Every failure event carries an attribution tag, so the agent's MOBF measures the agent — a dependency outage never poisons the reliability record of the system that suffered it.

Failure budget — floors set by ops capacity

TM-COPILOT
MOBF crit. 6,800 vs floor 4,000
Inside budget
SENTRY-VIS
MOBF crit. 2,500 vs floor 2,500 — drift is eating the margin
At the floor
CASE-AGENT
MOBF crit. 8,100 vs floor 3,000
Inside budget
ROUTE-OPT
MOBF crit. 5,000 vs floor 3,500
Inside budget

Floors work backwards from the operations team: exceptions they can absorb per day → maximum acceptable failure rate → minimum MOBF. Set before deployment, not discovered after.

Every active mode — trailing 12 weeks

Defects trend as rate per 1,000 attempts; waste as a measured level or $k per month. Select a tile to open the mode.

Efficiency

How much of every token, retry, and call turns into a successful outcome. Waste is measured as a level against your own best-decile baseline — dollars appear as supporting evidence, the levers are operational.

Output efficiency
Performance factor
71.0%
the efficiency third of OAE
Tokens per task
1.42×
vs best-decile baseline
Run efficiency
Retry rate
3.1%
of attempts need ≥1 retry
Cache hit rate
34%
of input tokens
Unit economics
Cost per successful task
$1.04
vs $0.79 per attempt
Recoverable
$10.9k/mo
high-addressability modes
Quality spend
Appraisal share
8.1%
checking our own work
COPQ · quarter
$32.5k
internal + external failure

Waste levels — vs your best-decile baseline

Levels, not invoices: each bar is how far the fleet runs above its own demonstrated best. Green means a lever is already working.

The causal edge that funds the work

FM-D-0015 · defect
Malformed JSON from parts-lookup
rate 6.5 → 1.9 /1k  −71%
causes ⟶
FM-W-0021 · waste
Retry amplification
$4,430 → $1,010 /mo  −$3,420

One root cause, one corrective action, one verification pass — worth 12% of failures and $49k a year.

Verification

Verified  CA-0141 · both series fell past the confidence bar after the Aug 1 effective date

Next candidate: FM-W-0026 → FM-W-0029 (r 0.81) — proposed on the registry, awaiting review

Edges draw automatically because defects and waste live in one registry — separate tools never see the line between them.

Cost per successful task — 12 weeks, all systems

Dotted line: cost per attempt ($0.79). The gap is what failures burn — CA-0141 closed a third of it.

Optimum availability — the economy of reliability

Cost of unreliability falls as investment rises; cost of achieving reliability climbs; the total-cost minimum sets the target — the same math reliability engineers use to set maintenance intervals.

Efficiency wins & levers in flight

Tool-contract hardening (CA-0141)
verified · retries down 75%
+$3.4k/mo recovered
Retrieval k 8 → 5
config change live Aug 10 · level watch running
measuring
Router tier for trivial subtasks (CA-0149)
inconclusive at current sample · window extended
remeasuring
Context policy (CA-0153 draft)
agent-drafted · awaiting ticket + effective date
≈$1.6k/mo ready

Every lever ships with a verification plan — the level vs baseline decides the verdict, the dollars just keep score.

Cost of Quality — Juran buckets, quarterly

COPQ = internal + external failure. Waste on successful runs is counted in the OAE Performance factor.

Waste modesmagnitude × addressability
IDWaste modeSystemRegimeLevel vs baselineMagnitudeAddressability

Corrective Actions

Actions live in your ticketing system. AIR links them to failure modes and computes the before/after on rate and cost once the effective date passes — the verdict doubles as the ROI record.

Jira sync — meridian.atlassian.net · project AIR · synced 4m ago

GitHub sync — 3 repos · webhooks on push + pull request

meridian/tm-copilot · meridian/sentry-vis · meridian/route-opt

Pull requests and commits that reference a mode, an action, or an owned path link automatically. Version-bump commits are flagged as population resets on the trend charts.

Last events

PR #438 opened 2h ago · push to tm-copilot 5h ago · PR #412 merge verified Aug 15

Actions5 linked · 2 verified · MTTR-E 11.5 days
IDCorrective actionModesTicketOwnerEffectiveVerification
Code changes touching failure modeslinked from GitHub · fixes and regressions both
ChangeRepoStatusModesActionImpact

AI Systems

Every occurrence and rate series is keyed to system, model version, prompt version, and config hash.

Systems4 connected
SystemTypeVersionFeederActive modesAttempts / wkOAEModel card

SALT Reliability · AIR · August 2026

The reliability platform for the AI era.

One product: AIR. Proven hardware FMEA, FRACAS, and CAPA disciplines, applied to AI systems that already sit in critical operations — with the evidence an auditor can read.

$4.9M
Y3 exit ARR
91%
Y3 gross margin
M24
First profitable month

Problem

AI is in critical operations. The reliability record is not.

Hardware reliability solved this sixty years ago: anticipate failure modes, capture what actually fails, drive root cause to a verified fix, and prove it. AI systems today are where hardware was before MIL-STD-1629 — deployed on vibes, failing in production, with no structured record of what failed, why, or what was done about it.

No engineering framework

There is still no standard way to apply FMEA, FRACAS, and CAPA to models, agents, and evals. Teams keep the story in tickets, slides, and memory.

Documents about AI, not from it

Generic GRC tools make you write policies. They do not mint the audit chain from the work of operating the system.

The mandate already exists

DoD TEVV has been in force since 2022. NIST AI RMF is the civilian counterpart. EU AI Act Article 50 transparency obligations apply from August 2026. The tooling to operationalize any of it does not.

Solution

AIR is the closed loop for AI reliability.

The first platform built around the DoD’s Responsible AI tenets — hardware FMEA/FMECA, FRACAS, and CAPA recast as AI Failure Mode & Risk Analysis, AI Incident Management, and Corrective Action & Traceability. Compliance evidence is a byproduct of operating the system, not a document authored after the fact.

AI-FMEA

Typed failure modes: hallucination, drift, adversarial manipulation, tool-contract failure, waste. S/O/D scoring survives. Detection maps to eval coverage and monitoring.

Incident management

Red-team findings, drift events, guardrail breaches, eval regressions, and field failures share one lifecycle: report, triage, RCA, CAPA, verify, close.

CAPA & traceability

Retrain, guardrail, prompt change, eval added, rollback, human-in-the-loop. Verification is the eval that caught it, re-run. The agent is included in Pro and above.

Why Now

Three converging forces

01

AI entering critical operations — without rigor

AI is being embedded into defense, aerospace, medical, and industrial systems. The DoD Responsible AI Strategy and Implementation Pathway — in force since 2022 — mandates TEVV across every AI program, with more than 60 lines of effort under CDAO oversight. NIST AI RMF is the civilian counterpart. EU AI Act Article 50 applies from August 2026; high-risk obligations were deferred to December 2027. No purpose-built tooling exists to operationalize any of it.

02

The stand-in tools are not a reliability record

AI GRC captures policy. Observability captures traces. MLSec captures attacks. AI SRE agents close infra incidents. Spreadsheets remain the default binder. None run failure mode → incident → RCA → CAPA → verification on AI behavior. Teams need a cloud-native reliability record, not another MTTR agent.

03

Just as no manufacturer ships a jet engine without failure analysis

No responsible organization will keep deploying AI into mission-critical environments without structured reliability assurance. That analogy is the translation, not a second product. Hardware reliability is how we already know this works. AIR is the company that makes it the default for AI.

Product

Cloud-native. AI-first. Compliance-ready.

AIR ships as multi-tenant SaaS: version-aware system registry, automated ranking, formatted report export, role-based access, and a Reliability Engineer Agent that surfaces insights without prompt engineering. LLM-agnostic architecture. On-prem for GOV/Defense from about Month 6. The clickable POC in this file is the product you can walk today.

What you can open now

AIR Core Feature workspace: five connected AI systems, a typed failure-mode registry, banded triage, reliability and efficiency views, and corrective actions with verification. Ask the agent about any mode, trend, or dollar figure.

What ships next

Month 5: AIR MVP in production. Year 2: TEVV module, AI system registry, Responsible AI tenet scorecard, red-team findings as a first-class incident. Year 3: standalone agent, traceability matrix, model-card generator, auto-formatted AI Act / DoD AI Review Board filings.

Innovation Pipeline

FRACAS and CAPA for AI — then stronger proof, then control before release.

NEAR · 0–6 MO

FRACAS and CAPA for AI

AIR is the system of record for how your AI fails. You classify failures, open corrective actions, and verify that rates and cost actually improved — the FRACAS/CAPA loop, built for AI products.

  • Failure Mode Registry
  • Auto-Group Repeat Failures
  • Reliability and Cost Scores
  • Safety-First Priority Ranking
  • Corrective Actions with Proof
  • AI System Inventory
  • Link Failures to Wasted Cost
  • Known-Error Playbooks
  • Starter Failure Catalog
  • Downloadable Reliability Report

For any company running AI in production: find the failure, fix it, prove it worked.

NEXT · 6–12 MO

Own the Evidence Stack

Collect only the signals AIR needs — including in locked-down networks — and turn every failure record into proof that maps to major AI rules and auditor packs.

  • Self-Hosted Collector
  • Map One Record to AI Rules — NIST, ISO 42001, EU AI Act, NAIC
  • Auditor Export Packs
  • Tamper-Evident Evidence Vault
  • Continuous Evidence Collection
  • Reliability Budget Alerts

Private networks can adopt AIR. Auditors get packs from real behavior, not checkbox screenshots.

LATER · 12–18 MO

Stop Bad Releases Early

Use the same failure catalog before launch. Simulate risks, block risky releases, and share failure knowledge across your systems and vendors.

  • Pre-Release Failure Analysis
  • Pre-Release Failure Simulation
  • Export Policies to Guardrails
  • Block Risky Releases
  • Shared Failure Libraries
  • Vendor AI Risk Tracking
  • Keep Rule Maps Current

Control moves before customers feel the failure — on the same FRACAS spine you already run.

Market

Platform TAM is hundreds of millions. $4.9M is the SOM plan.

Platform TAM for AI governance/assurance is about half a billion dollars in 2026 (Gartner ~$492M), growing toward $1B+ by 2030, with broader governance+compliance packs near $2.5B. AIR’s SAM is the operational reliability slice—defense, aerospace, and regulated enterprises that must run TEVV / NIST RMF / EU AI Act-style controls—~$30–80M, mid ~$50M via logo × ACV. SOM is $2–6M Y3 ARR independently; the company’s $4.9M Y3 exit ARR is a capture plan (~10% of mid SAM), not the market. We win on failure-mode → incident → CAPA → verification.

~$0.5B
TAM — AI governance/assurance platforms, 2026 (Gartner ~$492M)
~$50M
SAM mid — ops reliability slice; range ~$30–80M
$4.9M
SOM / company plan — Y3 exit ARR, not TAM
38%
Directional AI governance CAGR through 2030 — site claim; see Sources
TAM — platforms
AI governance / assurance platforms. ~$0.5B in 2026 → >$1B by 2030. Broader gov+compliance packs ~$2.5B (optional, not the primary TAM).
~$0.5B → $1B+
SAM — operational reliability
Defense/aerospace + TEVV / NIST RMF / AI Act enterprises that need a closed loop. Expandable via FS / insurance / healthcare / edu kits.
~$30–80M
SOM — SALT capture plan
Independent band $2–6M Y3 ARR. Company $4.9M Y3 exit ARR is upper-mid (~10% of mid SAM). Plan, not TAM.
$4.9M plan

One platform, vertical kits — not forks. Sequence: hold defense/aerospace, then Financial services (SR 26-2 genAI/agentic gap), Insurance (NAIC bulletin + 12-state 2026 exam pilot), Healthcare (FDA TPLC/PCCP + HIPAA), Education (FERPA/ED; partner-led). Kits expand SAM/SOM reach; they do not change published TAM.

DoD TEVV since 2022; EU Art. 50 Aug 2026; high-risk obligations deferred Dec 2027. Category is AI operational reliability / assurance — not whole GRC. Math, citations, and preexisting site claims (including the 38% CAGR) are on Sources.

Business Model

One rate card. Agent included. Capital efficient.

PLG entry on a card, expansion into enterprise and GOV. The Reliability Engineer Agent is included in Pro and above — not a $10K add-on. 3 people from Month 1. $500K pre-seed funds a 4-month build; AIR launches Month 5; $750K seed at Month 8 on live revenue. $1.25M total outside capital.

AIR rate cardAug 2026 model
TierACVBillingNotes
Starter$2,988$249/mo card5 AI Systems, 30-day trial, no AI features
Pro$6,000 – $7,200Annual $6k or $600/mo10 AI Systems; agent included; $995 training
Enterprise$35,000Annual10+ AI Systems, SSO; $10k training; agent included
Scale$125,000AnnualDedicated RDS, priority support; $20k training
GOV / Defense$150,00050% / 50% ATOOn-prem, air-gap, NIST RMF / 800-53 / CMMC / ITAR
Agent Add OnPremium agent capacity on Pro+
Add onACVBillingNotes
Agent Plus$6,000Dual billingPremium agent capacity on Pro+
Agent Unleashed$10,000AnnualMax agent capacity

Paying customers by tier — year-end (Y0–Y3)

0 100 200 300 400 4 Y0 52 Y1 78 88 178 Y2 195 163 392 Y3 launch
Customers by tierYear-end paying logos · bars sum to these totals
TierY0Y1Y2Y3
Starter12078195
Pro32988163
Enterprise—31026
Scale——15
GOV / Defense——13
Total452178392
AIR planY0 = M1–M7 · live figures from Summary
Y0 Y1 Y2 Y3
Recognized revenue$5.5K$399K$1.71M$3.98M
Gross margin—85%89%91%
Operating income($388K)($477K)$239K$1.66M
Ending cash$112K$689K$1.65M$4.47M
Exit ARR———$4.91M

Y0 gross margin is omitted: launch-month COGS sits on almost no recognized revenue. Y3 GM is 90.9%. The $3K/mo marketing plan includes a +30% customer-count uplift versus the no-uplift case — the aggressive assumption in the model. Year-end customer counts are the model’s per-tier mix (AWS customer table) × that 1.30x uplift, with former Agent-standalone logos counted as Pro. Y0 is the live M6–M7 platform MRR (1 Starter + 2 Pro at 1.0x). Bars sum to 4 / 52 / 178 / 392. Agent Plus and Unleashed are add-ons, not extra customers.

Traction

AIR POC live. Self-funded to this point.

The idea started in March 2026. This AIR workspace is the demo — built on founder time and personal capital. First paying customers follow the Month 5 launch. Seed at Month 8 is gated on AIR in production with live revenue.

  • Mar 2026 Idea started — Curtis Bise & Nick Cobb, remote, Texas, self-funded
  • Aug 2026 AIR POC live — this mockup, for investor and customer meetings
  • M1 $500K pre-seed · three people on payroll from day one (Curtis, Nick, Dev One)
  • M5 AIR launches after a four-month build
  • M6 AIR GOV / Defense on-prem · NIST RMF · 800-53 · air-gap-capable
  • M8 $750K seed on live revenue · ~3 months of AIR in production
  • M14–M24 SOC 2 Type II (~$35K) · NIST RMF / TEVV consultant ($50K, M14–M27)
  • M24 First profitable month · Y2 operating income positive
  • Y2–Y3 TEVV module, tenet scorecard, red-team incidents, then standalone agent and model cards

Team

The rare combination this problem requires
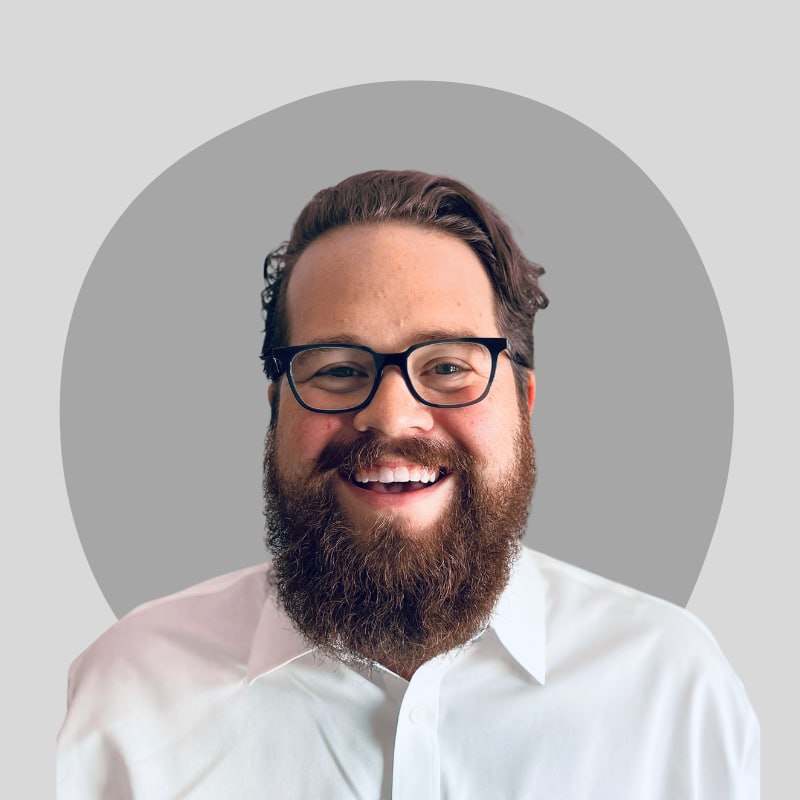
Building AIR takes credibility in reliability engineering and in shipping enterprise software. The co-founders bring exactly that — one from inside defense and aerospace reliability programs, one from eleven years building and scaling enterprise platforms. Remote, Texas. Dev One is the first engineer, unnamed, hired Month 1.

Curtis Bise

Curtis Bise

Co-Founder & Chief Executive Officer

Technology leader with 11+ years of enterprise-scale software experience. Currently Head of Customer Operations & CRM Technology at Inbenta, leading a globally distributed team of 25+ and reporting directly to the CEO. At GIACT, rose from System Administrator to SVP of Integrated Services — managing 100+ active client integrations, migrating 85% of business operations onto Salesforce, and overseeing a billing system that processed $50M in invoices annually. Named Employee of the Year in 2018 after relaunching the Salesforce organization in under three months. B.A.A.S. in Computer Systems Networking from the University of North Texas. Three Salesforce platform certifications.
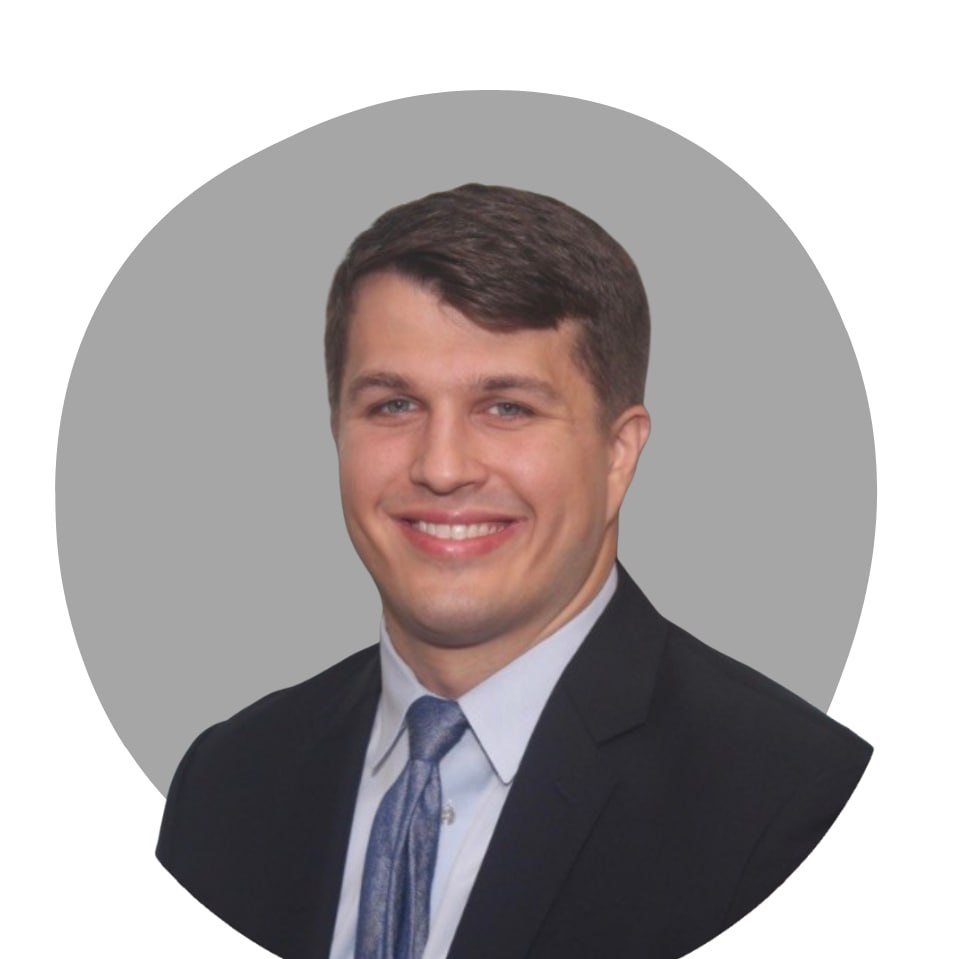
Nick Cobb

Nick Cobb

Co-Founder & Chief Reliability Officer

Reliability engineer with 8+ years supporting defense and aerospace programs across the full system lifecycle. At Raytheon Technologies and Bell Textron, stood up and maintained FRACAS programs across multiple platforms — including airborne targeting systems and military rotorcraft for U.S. Marine Corps programs — facilitated recurring Failure Review Boards, and led multi-disciplinary failure investigations. Performed reliability prediction analyses per defense acquisition requirements, flight qualification testing to MIL-STD-810G, and generated formal reliability deliverables for contract data requirements. Upon returning to Raytheon, stood up FRACAS programs on two active production programs and chaired weekly production Failure Review Boards. B.S. in Aerospace Engineering from Texas A&M University.

Competition

GRC writes documents about AI. AIR writes the record from operations.

AI GRC suites such as Credo AI capture policy, inventory, and assessments. Observability platforms such as Arize capture traces and evals. MLSec tools such as HiddenLayer red-team and defend at runtime. Spreadsheets are still the default binder. None of them run the failure-mode → incident → RCA → CAPA → verification chain. AIR is the first purpose-built AI reliability engineering platform.

AIR is AI reliability engineering — MTBF, a typed failure-mode registry, and traceable evidence — not AI SRE. AI SRE products optimize MTTR with agents that investigate infra incidents; borrow vocabulary where useful, but do not enter that category or invite an MTTR bake-off.

AI SRE closes the incident. AIR closes the loop.

Capability SALT AIR Credo AI Arize HiddenLayer Spreadsheets
Cloud-native SaaSYesYesYesYesNo
AI-powered triageYesLimitedYesNoNo
Closed loop (mode → incident → CAPA → verify)YesNoPartialNoNo
DoD TEVV / RAI officer toolingYesPolicyNoNoNo
Evidence from operations, not after-the-fact docsYesLimitedYesRuntimeNo
PLG entry + enterprise expansionYesTop-downYesTop-downn/a
On-prem GOV / air-gapM6YesYesPartialn/a

SALT marks reflect the AIR POC as of August 2026. On-prem GOV is Month 6 on the plan. Commercial deployment begins Year 1.

Adjacent (not AIR’s category)Feeder / watchlist
Capability SALT AIRAIR AI SRE agentsAI SRE Incident mgmtIncident
OptimizesMTBF + cost per successful taskMTTRCoordination / MTTR
Failure domainAI behavior & economicsInfra / servicesInfra incidents + comms
Persistent typed failure-mode registryYesNo (some memory / corpus)No typed ranked registry today
Closed loop (mode → CAPA → verify)YesPartial (remediate incident)Partial (retros / tickets)
Reliability growth / before–after proofYesNoNo
Evidence for audit / TEVV / program officeYesBlameless learning docsOps retros, not assurance record
Relationship to AIR—Feeder / integrationWatchlist if they add typed registry

Nearest corpus threat: incident-management vendors (PagerDuty, Rootly) already hold structured incident history and CAPA-adjacent workflows. If they add a persistent, typed, criticality-ranked failure-mode registry with trending, they approach FRACAS. Watch Rootly retrospectives and PagerDuty Insights. Resolve / Cleric / Causely remain integration targets, not rivals.

Causely’s persistent causal model is independent validation that structured failure knowledge beats re-deriving from raw signals every time — for infrastructure diagnosis. AIR is the system of record for AI behavior over time (rate, criticality, CAPA, verification), not a real-time causal inference layer.

The Ask

$500K pre-seed round

$500,000

Pre-seed on a post-money SAFE. Then a $750K seed at Month 8, gated on AIR in production with live revenue. $1.25M total outside capital. Illustrative caps in the model are $5M pre-seed / $12M seed — editable guesses, not a priced round. Founders remain ~74% fully diluted post-seed.

  • Four-month build; AIR launches Month 5. Year 0 is a build year by design, with a thin $5.5K of launch-month revenue.
  • Seed at Month 8 on live revenue. AIR GOV on-prem pulled forward to about Month 6 ($150K ACV).
  • SOC 2 Type II (~$35K, M14–M24) and NIST RMF / TEVV ($50K, M14–M27) clear enterprise and federal gates.
  • First profitable month M24. Y2 operating income +$239K. Y3 +$1.66M. $4.47M cash at M43. No follow-on required in the model.
  • Trough cash $112K at Month 7. Bridge protocol: $150–200K F&F/angel standby, arranged before Month 1, drawable only after cost levers.
$5M / $12M
Illustrative SAFE caps (model defaults)
~$16%
Investor ownership post-seed + 10% pool
$4.47M
Projected M43 cash on $1.25M raised
invest@saltreliability.com
Figures from the SALT Reliability AIR Model, August 2026 (Summary sheet). This material contains forward-looking statements. Actual results may differ. Caps are illustrative. Nothing here constitutes an offer to sell securities. Confidential — do not distribute. ·

Investor Info · Model · AIR · August 2026

AIR financial model

Website version of the SALT Reliability AIR Model, August 2026. Summary sheet is the source of truth. $1.25M total outside capital. Y0 = M1–M7, Y1 = M8–M19, Y2 = M20–M31, Y3 = M32–M43.

$1.25M
Outside capital ($500K M1 + $750K M8)
$4.91M
Y3 exit ARR
M24
First profitable month
$4.47M
M43 cash on the plan

P&L Summary

Year 0 through Year 3

Launch Month 5 after a four-month build. Year 0 is a build year by design. First profitable month is M24. Y3 gross margin 91%. Year-end customers: 4 / 52 / 178 / 392 (Starter, Pro, Enterprise, Scale, GOV).

Annual P&LLive from Summary / P&L_Summary
Y0 (M1–M7) Y1 (M8–M19) Y2 (M20–M31) Y3 (M32–M43)
Recognized revenue$5.5K$399K$1.71M$3.98M
COGS$9.1K$59K$188K$367K
Gross profit($3.7K)$340K$1.53M$3.61M
Gross margin—85%89%91%
Operating expenses$384K$817K$1.29M$1.95M
Operating income / (loss)($388K)($477K)$239K$1.66M
Operating marginn/m(120%)14%42%
Ending cash$112K$689K$1.65M$4.47M
Exit ARR (M43 MRR × 12)———$4.91M

Y0 gross margin is omitted: launch-month COGS sits on almost no recognized revenue. Y3 GM is 90.9%.

Cash, burn & runway

Trough at Month 7. Seed at Month 8. No follow-on in the model.

$500K at M1 covers the build with full founder salaries from day one. Trough cash is $112K at M7 — the thinnest point in the plan. $750K seed at M8 on live revenue. First profitable month M24. M43 cash $4.47M on $1.25M raised.

$435K
M1 closing cash after pre-seed
$112K
M7 trough (minimum cash M1–M43)
~$54K
Avg monthly burn M2–M7
~2 mo
Cushion at M7 at that burn

Cash position — quarterly closes (M1–M43)

$0 $1M $2M $3M $4M M1 pre-seed M7 trough M8 seed M43 $4.47M M1 M8 M19 M31 M43
Quarterly rollupRevenue, operating income, closing cash
M1–3 M4–7 M8–10 M11–13 M14–16 M17–19 M20–22 M23–25 M26–28 M29–31 M32–34 M35–37 M38–40 M41–43
Revenue $0$5.5K$47K$67K $119K$166K$243K$346K $494K$631K$737K$909K $1.12M$1.22M
Op. income ($171K)($217K)($174K)($129K) ($101K)($73K)($123K)($16K) $137K$241K$164K$334K $534K$632K
Closing cash $329K$112K$735K$718K $657K$689K$637K$770K $1.21M$1.65M$2.02M$2.47M $3.48M$4.47M

Y2 salary step at M20 (founders $250K) shows up as the M20–M22 operating-income dip while cash stays above $600K. Profitability holds from M24.

Rate card

AIR pricing, including Pro dual billing

The Reliability Engineer Agent is included in Pro and above. Agent add-on revenue is bundled. Mix: 50% of Pro on monthly, 50% on annual prepay.

AIR rate cardAug 2026 model
TierACVBillingTrainingNotes
AIR Starter$2,988 ($249/mo)Monthly card$05 AI Systems, capped storage, no AI features; 30-day trial
AIR Pro — monthly$7,200 ($600/mo)Monthly card$99510 AI Systems, AI automation (token-limited); agent included
AIR Pro — annual$6,000Annual prepay$99510 AI Systems; 16.7% discount vs monthly; agent included
AIR Enterprise$35,000Annual prepay$10,00010+ AI Systems, SSO, integrations; agent included
AIR Scale$125,000Annual prepay$20,0002x tokens/storage, dedicated Multi-AZ RDS, priority support
AIR GOV / Defense$150,00050% signature / 50% ATO+3mo$20,000On-prem, air-gap, NIST RMF / 800-53 / CMMC / ITAR
Agent Add OnPremium agent capacity on Pro+
Add onACVBillingTrainingNotes
Agent Plus$6,000 or $550/moDual billing$0Premium agent capacity for Pro and above
Agent Unleashed$10,000Annual only$0Max agent capacity; adoption ~1/2 of Agent Plus

Usage metering is billed monthly in arrears above the included allocation. Flat add-ons: Priority Support $15K (Enterprise+), DB Isolation $6K, 25% attach. 5% annual escalator on annual tiers.

Customers

Year-end logos by AIR tier

Same mix as Plan. 1.0x counts from the model’s per-tier AWS customer table, × the +30% uplift already in live revenue. Former Agent-standalone customers are Pro. Y0 from M6–M7 platform MRR. Agent Plus and Unleashed attach to Pro+ — they are not extra logos.

Paying customers by tier — year-end (Y0–Y3)

0 100 200 300 400 4 Y0 52 Y1 78 88 178 Y2 195 163 392 Y3 launch
Customers by tierYear-end paying logos · bars sum to these totals
TierY0Y1Y2Y3
Starter12078195
Pro32988163
Enterprise—31026
Scale——15
GOV / Defense——13
Total452178392

1.0x year-bucket mix: Starter 15 / 60 / 150, Pro 20 / 60 / 110, Enterprise 2 / 8 / 20, Scale 0 / 1 / 4, GOV 0 / 1 / 2, plus Agent-standalone 2 / 8 / 15 folded into Pro. × 1.30, rounded to whole logos. Y0: 1 Starter + 2 Pro at 1.0x from M6–M7 MRR ($1,039 + $1,754 = $2.8K platform revenue).

Revenue build

Annual revenue by stream

AIR platform tiers include Pro repricing. Training is the AIR share. Consulting is held flat in sensitivity cases.

Recognized revenueLive from Monthly
Y0Y1Y2Y3
AIR platform tiers (incl. Pro repricing)$2.8K$228K$1.20M$3.13M
AIR flat add-ons—$9.7K$47K$119K
AIR usage metering$0.1K$6.2K$35K$112K
AIR Pro (agent included)—$12K$56K$115K
Training (AIR share)$2.6K$72K$216K$231K
Consulting—$50K$65K$80K
Agent Plus—$12K$54K$110K
Agent Unleashed—$9.2K$43K$87K
Total revenue$5.5K$399K$1.71M$3.98M

Headcount

Three people from Month 1. Hiring ramp funded from revenue.

Curtis, Nick, and Dev One are paid full salaries from M1 — no pre-seed discount. Founder salaries are $200K in Y1, then step to $250K at M20 and $350K at M32; recommend milestone-conditioning in founder agreements ($250K on 2 consecutive profitable months; $350K on $2.5M ARR run-rate). Dev One is $150K through Y1, $165K in Y2, and $175K in Y3. Additional team is loaded cost, not named seats.

Compensation ladderBase salary, not loaded
Pre-seed (M1–M7)Y1Y2Y3
Curtis — CEO$165,000$200,000$250,000$350,000
Nick — Co-founder / CRO$165,000$200,000$250,000$350,000
Dev One — Engineer$150,000$150,000$165,000$175,000
Health insurance (company-paid)$800/person/mo$800/person/mo$800/person/mo$800/person/mo
Employer payroll tax7.65%7.65%7.65%7.65%
Additional team (loaded $/mo)—$0$30,000 (~2–3)$70,000 (~5–6)
Loaded team cost by yearFrom Monthly
Y0Y1Y2Y3
Core team comp$337K$653K$783K$1.02M
Additional team——$360K$840K

Operating costs

Lean OpEx. Marketing at $3K/mo from launch.

SOC 2 (~$35K, M14–M24) and NIST RMF / TEVV ($50K, M14–M27) clear enterprise and federal gates. Negative payroll-and-misc lines in later years are source-model allocations, not cash inflows.

Operating expensesAnnual rollup from Monthly
Y0Y1Y2Y3
Team comp$337K$653K$783K$1.02M
Additional team——$360K$840K
Marketing$9K$36K$36K$36K
SaaS / tools$5K$12K$12K$12K
Insurance$3.5K$15K$15K$15K
Legal — ongoing$5.3K$24K$24K$24K
Legal — formation & seed$10K$20K——
Bookkeeping & tax$2.1K$12K$12K$12K
NIST RMF / TEVV consultant—$21K$34K$15K
Equipment$9K—$6K$6K
Travel & conferences$1.5K$12K$18K$18K
Payroll & misc admin$1.8K($7.2K)($39K)($57K)
SOC 2—$19K$26K$10K
Total OpEx$384K$817K$1.29M$1.95M
COGSAWS + Stripe
Y0Y1Y2Y3
AWS base$9.0K$49K$145K$259K
AWS variable—$1.5K$8.8K$28K
Stripe (2% of revenue)$0.1K$8.0K$34K$80K
Total COGS$9.1K$59K$188K$367K

Cap table

Illustrative SAFE conversion at seed

$1.25M on SAFEs at the model’s default caps ($5M pre-seed / $12M seed) is about 16% to investors plus a 10% pool, leaving founders ~74% combined. Simplified cap-based conversion; no discount, no MFN, single trigger.

Assumptions
Pre-seed SAFE cap$5.0M
Seed SAFE cap$12.0M
Option pool (post-seed target)10%
Dev One grant (from pool)1.5%
Ownership, fully diluted post-seed
Pre-seed SAFE holders10.0%
Seed SAFE holders6.25%
Option pool10.0%
Founders (Curtis + Nick)73.75%
…each (50/50)36.88%

Caps are editable guesses; no round is priced yet. Price a real round with counsel.

Sensitivity

Uplift, seed size, and OpEx. Consulting held flat.

Revenue and variable costs scale roughly linearly with customer uplift; fixed costs do not. Cash effects flow at ~92% of the operating-income delta (deferral offset). Seed cash at every point moves dollar-for-dollar from M8.

Customer-uplift sensitivity (linearized)Current plan is 1.3x
Low 1.0xCurrent 1.3xHigh 1.6x
Y1 revenue$318K$399K$479K
Y2 revenue$1.33M$1.71M$2.09M
Y3 revenue$3.08M$3.98M$4.88M
Y1 operating income($551K)($477K)($403K)
Y2 operating income($127K)$239K$604K
Y3 operating income$756K$1.66M$2.57M
M43 cash (approx.)$3.22M$4.47M$5.71M
Seed sizeExact from M8
SeedM19 cashM43 cash
$500K$439K$4.22M
$650K$589K$4.37M
$750K$689K$4.47M
$1.00M$939K$4.72M

A 3-month seed slip past M8 is survivable from the M7 trough; each month of delay costs ~$45K of deferred comp step-up and stretches residual burn ~$8–10K/mo.

OpEx delta from M8Extra / (saved) $/mo
Δ $/moM19 cashM31 cashM43 cash
−$10K$809K$1.89M$4.83M
+$10K$569K$1.41M$4.11M
+$25K$389K$1.05M$3.57M
+$50K$89K$445K$2.67M

Downside playbook & bridge protocol

Pre-negotiated levers so a seed slip is not existential

The lean plan has no institutional pre-seed investor to draw from. Standby bridge commitments should be arranged before M1 from friends-and-family / angels.

Triggers (check monthly)

T1 — M7 cash below $120K with seed not yet signed. T2 — first 90 days post-launch: paying customers < 8 or MRR < $6K. T3 — M12 revenue run-rate < 60% of plan. T4 — seed slips past M10.

Levers, in order (monthly savings)

L1 freeze marketing ($3K). L2 defer travel ($1.5K). L3 defer NIST consultant to M18 ($3.6K in-window). L4 hold salary step-2: founders stay at $200K past M20 ($9.0K). L5 push consulting to the $80K/yr cap. L6 delay hiring ramp one quarter ($30K/mo in Y2).

Structural responses

T2+T3 together: the +30% uplift thesis is wrong — recut at 1.0x and Y2 hiring to $15K/mo. T4: L1–L4 extend the trough 5+ months without touching the team; draw the bridge only after L4. If GOV interest outruns commercial: pull NIST forward, push Iron Bank, let SBIR carry the gap.

Bridge protocol

$150–200K across 2–4 parties; SAFE at the seed cap with a 10% additional discount; $50K tranches on written notice; expires M12. Draw only if cash < $120K, seed process is active (or MRR > $8K), and L1–L4 are already exercised. Converts at seed close. Owner: Curtis, commitment letters before M1.

Figures from the SALT Reliability AIR Model, August 2026 (Summary sheet is the source of truth). Forward-looking statements; actual results may differ. Caps are illustrative. Nothing here constitutes an offer to sell securities. Confidential — do not distribute. ·

Investor Info · Sources · AIR · September 2026

Market math and citations

Investor-honest documentation of TAM / SAM / SOM, bottom-up math, preexisting site claims, and the regulation hooks behind the multi-market sequence. Dollar figures below are third-party estimates or the company plan — not audited by SALT.

Category definitions

TAM vs SAM vs SOM

AIR is an AI operational reliability / assurance platform: a closed loop from failure mode → incident → CAPA → verification. That is not whole GRC, not observability, not MLSec, and not AI SRE. Competitors stay Credo / Arize / HiddenLayer / spreadsheets; AI SRE agents and incident-management tools are adjacent feeders, not the category.

How we use the wordsAIR category
LayerDefinition on this siteAIR number
TAM Spend on AI governance / assurance platforms (primary). Broader governance+compliance packs are optional context, not the operating TAM we sell first. ~$0.5B (2026) → >$1B by 2030; broader pack ~$2.5B
SAM Defense / aerospace + TEVV / NIST RMF / EU AI Act-style enterprises that need an ops reliability closed loop. Vertical kits (FS, insurance, healthcare, edu) expand reach; they do not republish TAM. ~$30–80M; mid ~$50M
SOM What SALT can capture. Independent band is $2–6M Y3 ARR. The $4.9M figure on Plan / Model is the company capture plan — SOM, not TAM. $2–6M independent; $4.9M plan

Top-down TAM

Platform sizing and the reports behind it

Primary TAM is AI governance / assurance platforms. We do not invent a SALT-computed 2030 dollar figure from the old 38% CAGR claim. Analyst packs disagree on definition and year; the stack we use on Market is the researched range below.

Figures used on MarketNo extra $ beyond this research
ItemFigureSourceDate / note
AI governance / assurance platforms (primary TAM) ~$0.5B in 2026 → >$1B by 2030 Researched stack; Gartner platforms figure as the 2026 anchor 2026 / 2030
Gartner AI governance platforms ~$492M (2026) Axis Intelligence (cites Gartner Feb 2026) Feb 2026 citation
Broader governance + compliance packs ~$2.5B Optional wider pack — not the primary platform TAM Contextual only
38% AI governance CAGR through 2030 Directional site claim only Preexisting airdemo Market blurb. Keep as growth color; do not treat as a SALT forecast or a computed 2030 TAM. Historical / site claim
Category reports used to triangulateCited; figures not restated unless in the research stack
PublisherReportURL
Mordor Intelligence AI Governance Market mordorintelligence.com/industry-reports/ai-governance-market
Mordor Intelligence AI Governance Platforms Market mordorintelligence.com/industry-reports/ai-governance-platforms-market
Grand View Research AI Governance Market grandviewresearch.com/industry-analysis/ai-governance-market-report
Global Market Insights AI Governance Market gminsights.com/industry-analysis/ai-governance-market
The Business Research Company AI Governance Global Market Report thebusinessresearchcompany.com/report/ai-governance-global-market-report
New Market Pitch AI governance is growing (commentary) newmarketpitch.com/blogs/news/ai-governance-is-growing

Definitions of “AI governance” vs “platforms” vs “governance + compliance packs” are unstable across houses. That is why Market leads with the platform stack (~$0.5B → $1B+) and labels the ~$2.5B pack as broader context.

Bottom-up SAM

Logo × ACV, then a segment check

SAM is constructed from buyers who need the closed loop, not from a percent of TAM. Assumptions are stated; they are not a census.

Base caseMid ~$50M
AssumptionValueNote
Addressable logos~1,000Defense / aerospace + regulated enterprises that must prove TEVV / NIST RMF / AI Act-style controls
Blended ACV~$50kMix of Pro / Enterprise; GOV is a smaller count at a higher ACV
SAM~$50M1,000 × $50k
Segment check (sums to the same mid)~$50.4M
SegmentLogosACVSAM
GOV-capable80$120k$9.6M
A&D commercial120$40k$4.8M
Regulated enterprise800$45k$36M
Total1,000—~$50M
BandConservative / optimistic
CaseMathSAM
Conservative400 logos × $40k$16M
Mid1,000 logos × $50k$50M
Optimistic1,600 logos × $50k$80M

Published SAM on Market is ~$30–80M (mid ~$50M). The conservative $16M case is a tighter filter, not a second published SAM. Vertical kits expand the logo set over time; they are not added into the 2026 TAM.

SOM / SALT $4.9M model

Company plan, not the market

Independent SOM is $2–6M Y3 ARR. The $4.9M / $4.91M Y3 exit ARR on Plan and Model is the Aug 2026 AIR model — a capture plan at about 10% of mid SAM. Label it SOM everywhere it is used as a market number.

SOM stackAug 2026 model
ItemNumberWhat it is
Independent Y3 SOM$2–6M ARRWhat a focused team can reasonably capture in three years
SALT Y3 exit ARR$4.9M ($4.91M on the model sheet)Company plan. Upper-mid of the independent band. ~10% of ~$50M mid SAM.
Source of $4.9MAIR Plan / Model on this demoSALT Reliability AIR Model, August 2026 (Summary sheet). Rate card on the same pages.
AIR rate card (preexisting — preserved)Aug 2026 model
TierACVNotes
Starter~$3k ($2,988)$249/mo card; 5 AI Systems
Pro$6–7.2kAnnual $6k or $600/mo; agent included
Enterprise$35kAnnual; 10+ AI Systems, SSO
Scale$125kAnnual; dedicated RDS
GOV / Defense$150k50% / 50% ATO; on-prem / air-gap

Rate card and $4.9M remain on Plan and Model unchanged. This page only clarifies that those dollars are SOM / plan, not TAM. .

Preexisting site claims

What the demo already said, and how we treat it now

InventoryPlan / Model / Why Now preserved; Market + Sources clarified
Claim on siteWhere it still appearsVerification / correction
$4.9M three-year SOM / Y3 exit ARR Plan hero, Model, Business Model, Market Company plan from the Aug 2026 AIR model. Keep the number. On Market / Sources it is labeled SOM / plan, not TAM.
Rate card: Starter ~$3k, Pro $6–7.2k, Enterprise $35k, Scale $125k, GOV $150k Plan Business Model; Model Rate card Unchanged. Source: this demo’s Aug 2026 rate card tables.
“38% AI governance CAGR through 2030” Was the Market headline stat; still shown as directional Keep as growth color. Add the 2026 platform base (~$492M Gartner via Axis Intelligence). Do not multiply CAGR into a new SALT 2030 TAM. Analyst CAGRs disagree.
DoD TEVV in force since 2022 Problem, Why Now, Product, Market Consistent with DoD Responsible AI Strategy and Implementation Pathway (CDAO). See regulation table.
EU AI Act Art. 50 from Aug 2026; high-risk deferred Dec 2027 Problem, Why Now, Market Preexisting site claim, retained. Annex III is the high-risk list we cite. Transparency (Art. 50) vs high-risk duties are different clocks.
Competitors: Credo / Arize / HiddenLayer / spreadsheets Competition slide Correct category framing. AI GRC / observability / MLSec / binders — not hardware RAMS. AI SRE agents and incident mgmt sit in a second Adjacent table (not extra columns). Adjacent market $ is not AIR TAM.

Vertical regulation hooks

Why the kits exist

Hold defense/aerospace. Then attach a kit — not a fork — when the buyer already has a named control. Citations are the hooks, not a claim that AIR is a GRC suite for that vertical.

Cross-cuttingAlready on Why Now
HookWhat it isURL
NIST AI RMF NIST.AI.100-1 and the RMF landing page. Civilian counterpart to DoD TEVV language on this site. doi.org/10.6028/NIST.AI.100-1
nist.gov/itl/ai-risk-management-framework
EU AI Act Annex III High-risk use-case list. Site claim: Art. 50 transparency Aug 2026; high-risk duties deferred Dec 2027. artificialintelligenceact.eu/annex/3/
DoD RAI / TEVV Responsible AI Strategy and Implementation Pathway. Site claim: TEVV since 2022, CDAO oversight. 2024-06 RAI Strategy Implementation Pathway (PDF)
Sequence after defense / aerospaceKits expand SAM/SOM, not TAM
VerticalHookURL
Financial services OCC Bulletin 2026-13; Federal Reserve SR 26-2 (genAI / agentic gap). occ.gov … bulletin-2026-13.html
federalreserve.gov … SR2602.pdf
Insurance NAIC model bulletin on the use of AI by insurers; AI topic page; 12-state 2026 exam pilot summary. Colorado SB21-169 as a state unfair-discrimination hook. NAIC model bulletin
NAIC AI topic
Pilot Project Summary (PDF)
Colorado SB21-169
Healthcare FDA AI-enabled device software functions (lifecycle / TPLC) and PCCP; HIPAA business associates. FDA AI-DSF lifecycle guidance
FDA PCCP (media/166704)
HHS HIPAA business associates
Education (partner-led) FERPA vendor FAQ; ED AI Dear Colleague letter. FERPA Vendor FAQ (PDF)
ED AI DCL (PDF)

Adjacent markets

Not AIR TAM

Observability, MLSec, and Responsible AI / GRC platforms are competitive adjacency. Their analyst dollars are not added into AIR TAM, SAM, or SOM.

Named adjacency onlyDo not roll into AIR TAM
AdjacencyWhy it is not AIR TAMCitation
AI observability Traces, evals, token telemetry. Arize sits here. No failure-mode → CAPA → verify loop. MarketsandMarkets AI Observability
NextMSC AI Observability
AI / ML security Runtime defense and red-team. HiddenLayer sits here. FMI AI Security Platforms
HiddenLayer Series B
Responsible AI / AI GRC platforms Policy, inventory, assessments. Credo sits here. Documents about AI, not the reliability record from operating it. Credo AI funding context (Jul 2024)

Adjacent (not AIR TAM)

Adjacent: AI SRE and incident management (not AIR TAM)

AI SRE (“AI for SRE”) is a funded adjacent category: agents that triage and remediate infrastructure incidents. That is not AIR’s category and not AIR’s TAM.

Named adjacency onlyDo not roll into AIR TAM
NameRole vs AIRCite carefully
Resolve AI and pure-play AI SRE agents Feeder — incident narratives in; not a substitute for the registry Vendor funding/news; do not restate unverified customer % as SALT fact
Cleric Nearest neighbor on cross-incident memory; still not typed FRACAS Product positioning
Causely Thesis cousin: persistent failure/causal model vs per-query reconstruction; infra diagnosis, not AI behavioral SoR arXiv 2605.18327 (vendor-authored); Causely seed materials
PagerDuty / Rootly Corpus / workflow watchlist Product docs

Market maps from Mezmo and Bronto are vendor-published; useful taxonomy, interested conclusions. Do not treat vendor benchmarks (DoorDash MTTR claims, Dynatrace 12×, Causely token tables) as SALT-validated.

Disclaimer

How to read the dollars

Analyst estimates disagree. Category definitions are unstable (“AI governance,” “platforms,” “governance + compliance”). Dollar figures on Market and this page come from third parties or from the SALT Aug 2026 company model. They have not been audited by SALT. The $4.9M Y3 exit ARR is a capture plan (SOM), not TAM. Adjacent observability / MLSec / GRC / AI SRE market sizes are shown only to locate competitors or feeders — not AIR TAM. Vendor maps and MTTR benchmarks are not SALT-validated. Nothing here is an offer to sell securities. Confidential — do not distribute.